Forecasting sounds mystical until you look at how a tournament works. Participants do not simply announce who will win an election or how much a movie will make. They assign probabilities to uncertain outcomes, update those probabilities as information changes, and are scored after events resolve.
Metaculus says bots finished first and second overall in its Summer 2026 Cup, with ManticAI second. Mantic says it beat 676 human participants, while Metaculus reports 885 forecasters made forecasts across 58 questions. The result is evidence about one scored forecasting tournament, not proof that AI can predict markets, politics or business in general.1, 2
What happened in the Summer 2026 Cup
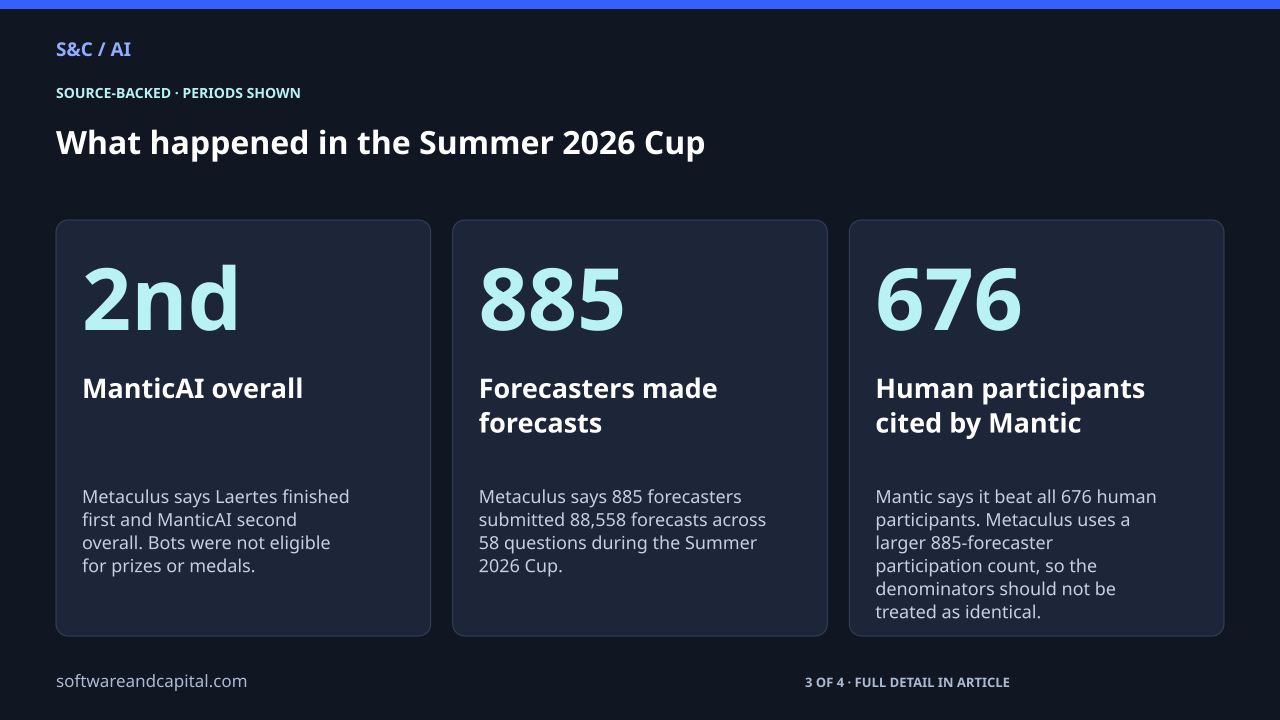
Metaculus says Laertes finished first and ManticAI second overall. Bots were not eligible for prizes or medals.
Metaculus says 885 forecasters submitted 88,558 forecasts across 58 questions during the Summer 2026 Cup.
Mantic says it beat all 676 human participants. Metaculus uses a larger 885-forecaster participation count, so the denominators should not be treated as identical.
Forecasting is about probabilities, not confident guesses
A forecaster might assign a 70% chance to one outcome and later move to 55% when new evidence arrives. Scoring rewards probabilities that are well calibrated to what eventually happens. That makes the task different from generating a plausible explanation after the fact.
| Behavior | Good forecasting habit | What it is not |
|---|---|---|
| Assign probabilities | Express uncertainty numerically | A single confident prediction |
| Update forecasts | Respond when evidence changes | Locking in the first answer |
| Score after resolution | Reward probabilities closer to outcomes | Judging prose quality |
| Aggregate many questions | Test consistency across events | Proof of universal predictive ability |
The tournament covered very different kinds of questions
Metaculus says the Summer Cup contained 58 questions. Mantic highlights examples spanning elections, technology and box-office outcomes. That breadth is part of the appeal, but it also means the result is an average across a particular question set, scoring system and time period.1, 2
The denominator is less tidy than the headline
Mantic describes beating 676 human participants. Metaculus says 885 forecasters made forecasts during the tournament and separately reports that bots took first and second overall. Those statements can coexist if participation and leaderboard eligibility differ, but the public pages do not make the denominator mapping obvious enough to collapse into one universal count.1, 2
One tournament does not prove AI predicts everything better
A strong result can show that an AI system performed well under a defined forecasting protocol. It does not automatically transfer to stock prices, a company’s sales forecast or a political race outside the tournament. Different domains have different data, incentives and feedback loops.
What would make the claim stronger
- Repeated top performance across multiple independent forecasting tournaments.
- Clear reporting of which questions, participants and scoring windows are included in each comparison.
- Results against expert forecasters as well as broad community participants.
- Evidence that the system remains calibrated when events are rare, ambiguous or structurally different from its training examples.
That distinction is similar to evaluating AI agent success claims: a benchmark is useful when its task, denominator and scoring rule stay visible. The interesting question is not whether AI can ‘see the future.’ It is whether probabilistic forecasting becomes a measurable capability that keeps improving.
Sources and methodology
Sources checked September 26, 2026. Dates and periods for individual figures are stated beside them.
- Metaculus: Summer 2026 Cup winners ↗Accessed 2026-09-26
- Mantic: $25 million financing and Metaculus Cup result ↗Accessed 2026-09-26
Scope and assumptions
The 676-human figure comes from Mantic, while Metaculus reports 885 forecasters overall. The public pages do not fully reconcile those denominators.
The tournament result does not establish that Mantic or forecasting AI is superior across financial, political or business forecasting generally.
Bots were not eligible for Metaculus prizes or medals even though they appeared in the overall performance comparison.
Continue reading
86% Agreement Can Still Miss Half the AI Failures →
1 in 4 Workers Is Exposed to AI. That Is Not a Layoff Forecast →